


Models Stuck in Notebooks
Models that work in testing never reach production without an MLOps pipeline.
Our MLOps consulting services build the pipelines, deployment automation and monitoring that keep machine learning models and AI agents reliable, affordable and ready to scale. We work with the cloud, tools and models you already use, so AI keeps working after launch instead of quietly breaking.
MLOps Challenges
Why AI models that work once often fail at scale, and how MLOps fixes it.
Models that work in testing never reach production without an MLOps pipeline.

Without model monitoring, accuracy drifts and nobody notices until customers do.

Hand-offs create fragile, one-off scripts. MLOps gives both teams one workflow.
Unplanned GPU and inference usage pushes cloud bills up. AI infrastructure needs cost controls.
Book A Call
MLOps Services
We build and manage the infrastructure, deployment pipelines, monitoring, governance, and optimization needed to run AI systems reliably in production.
MLOps strategy and assessment: a review of your setup and a practical MLOps roadmap.
ML model deployment services: automated pipelines that take models from training to production safely.

Machine learning model monitoring services that track accuracy, drift, latency and cost, with alerts.

LLMOps services: prompt versioning, evaluation, guardrails and cost tracking for LLM applications.

AI infrastructure engineering: scalable cloud and GPU infrastructure on AWS, Azure or Google Cloud.
AI cost optimization that right-sizes infrastructure and model usage without hurting quality.
MLOps Process
A three-phase approach that moves you from one-off scripts to governed, repeatable AI operations.

Timeline: 1-2 weeks
We review your models, data pipelines, cloud setup and release process, and design the MLOps roadmap.
Deliverables:

Timeline: 3–6
We build automated training, testing and deployment pipelines with model monitoring.
Deliverables:

Timeline: 6 weeks and ongoing
We run, monitor and improve your AI infrastructure, keeping models accurate and costs under control.
Deliverables:
MLOps Benefits

Ship model updates in hours instead of weeks.
Model monitoring catches drift and failures early.
See exactly what your AI infrastructure costs and why.
Data scientists and engineers share one MLOps pipeline.

Versioning and logs show which model made which decision.
MLOps Use Cases
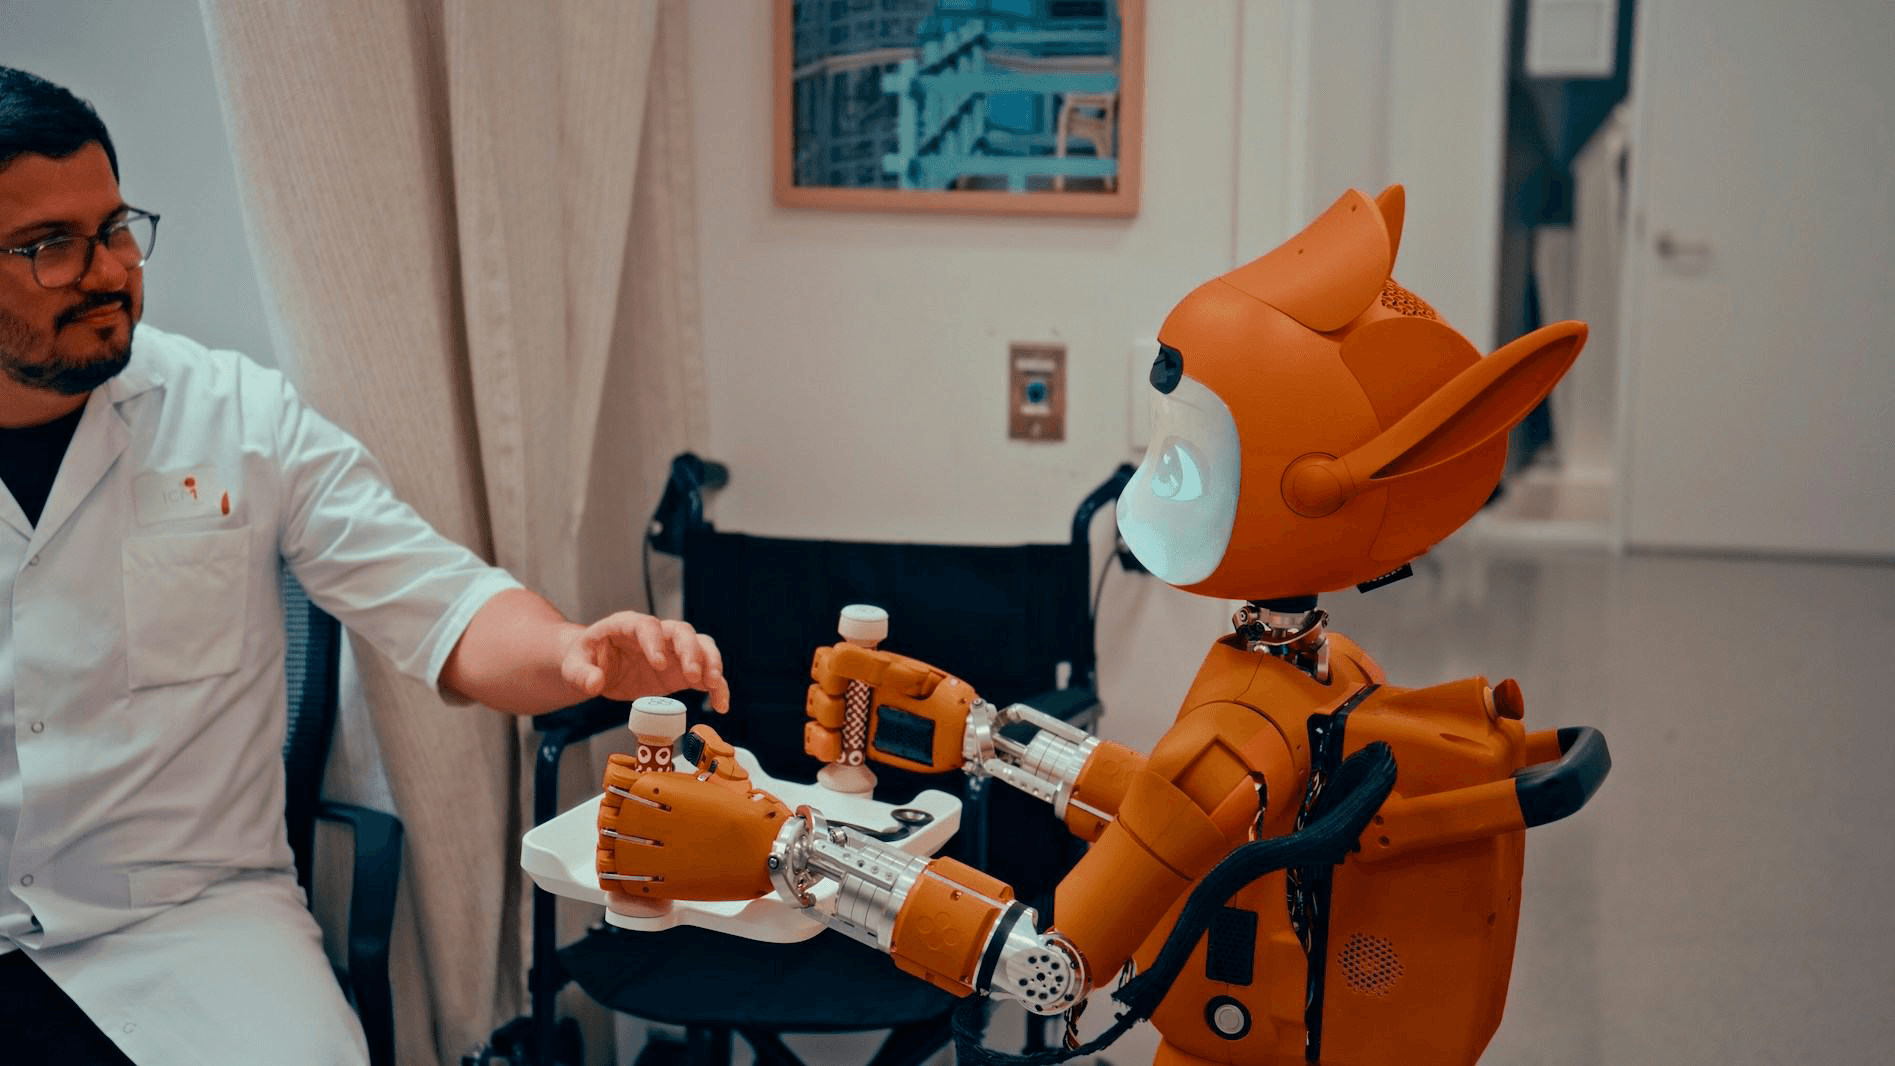

MLOps for healthcare: auditable AI infrastructure and model monitoring for clinical and operational models.
 MLOps for clinical and operational models.Model monitoring with audit logs for healthcare.Secure AI infrastructure for patient data.Retraining pipelines with clinical review steps.
MLOps Tech Stack
We use proven, production-grade tools and choose the right model for each job based on accuracy, cost and privacy.


MLOps FAQs
Answers to common questions about mlops services, including cost, timelines and how we work.
MLOps (machine learning operations) is the set of practices and tools used to deploy, monitor and maintain machine learning models in production. It matters because models degrade over time as data changes. MLOps automates releases, tracks performance and catches problems early, so AI stays accurate, reliable and cost-effective.
Yes, we build within AWS, Azure, or GCP depending on where your systems already live.
We set up automated evaluation checks and usage dashboards that flag drops in accuracy or response quality.
DevOps automates how software code is built, tested and released. MLOps applies the same ideas to machine learning, but also manages data, model training, versioning and monitoring for accuracy and drift. Software behaves the same until code changes; models can get worse on their own as real-world data shifts.
We build rollback procedures into the pipeline so a bad deployment reverses quickly, with the team alerted.
We build cost dashboards and tiering strategies so spend is visible and predictable, not a surprise.
Package the model with its dependencies, test it against real data, then release it through an automated pipeline, usually as an API or batch job on scalable cloud infrastructure. After release, monitor accuracy, latency and cost, and keep a rollback plan and retraining process ready.
Novatore's rates are $25 to $49 per hour. Most MLOps work starts with a short assessment of your current models and pipelines, followed by a phased build plan.
Why Novatore for MLOps
We combine strategy and delivery to build what actually ships, from roadmap to production.

Strategists, engineers, and QA specialists work as one team to turn plans into software fast.

React, Next.js, Node.js, Flutter, and Laravel expertise, paired with modern AI and cloud tooling, covers the full delivery lifecycle.

We work inside the timelines, communication norms, and compliance expectations our North American and UK clients require.

50+ products delivered from concept to production across HealthTech, FinTech, retail, and SaaS, with proven experience.
We Are Just One Click Away
Tell us how your models run today. We'll show you what it takes to make them reliable, monitored and cost-efficient.
CONTACT US
Have a challenge worth solving or an idea worth building? Let's explore it, shape it, and turn it into a solution that creates real impact.
